
 E-Paper


Off the Charts newsletter: A post mortem of our election model
Dan Rosenheck, our data editor, considers why our election forecast missed the signs of the tsunami


 Prefer HTon Google


Republicans weren’t the only losers in America’s midterm elections this week. Spare a tear for The Economist’s congressional model, which was the most conservative of all public forecasts on the expected size of the Democratic wave. Our final predictions gave the party only a 52% chance of winning the Senate, compared with 65-85% for most competitors. And although we did assign a respectable 8% chance to the possibility of Democrats claiming at least the 56 Senate seats they are now expected to have won, there is no such solace for our House forecast. Democrats are on track to secure 260 seats in the lower chamber, one more than the top of our 95% prediction interval.What went wrong? Our model takes a fundamentally different approach to other congressional forecasts, which is why it differs sharply from the consensus. Other models are generally “bottom-up”, which means that they first try to predict the result of each legislative contest, and subsequently estimate the national popular vote as a byproduct of their seat-level forecasts. This approach relies on an assumption that most forecasters take as gospel: polling errors are inevitable, but neither their direction nor their size can be predicted.In contrast, our “top-down” method arrogantly rejects this axiom. It starts with a model of the overall popular vote that attempts to predict which party will do better than national polls suggest, and by how much. It then assumes that this expected error will be reflected in individual races, shifting all of their results by a corresponding amount. In some years, like 2022, this has increased my estimates for the party that beat expectations (Democrats) and made our predictions unusually accurate. This time, however, I got my comeuppance.
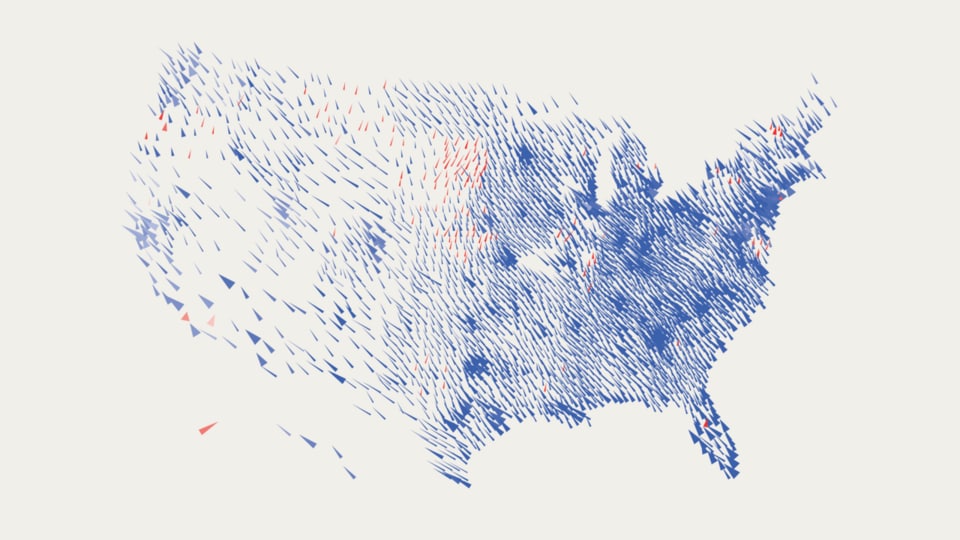
Our forecast accounts for the persistent biases that polls have often displayed in congressional races. The strongest pattern is that generic ballot surveys, which ask respondents which party they plan to back for Congress, tend to overestimate support for whichever side is ahead (see chart above). On average, parties’ eventual margins of victory have been only half as big as polls implied. We also incorporate presidential-approval ratings and the results of special elections for vacant legislative seats into our model.Because of the generic ballot’s history of inaccurate exuberance, our model usually assumes that a wave will crash ashore with less force than others predict. Two years ago, I wrote in this newsletter that I was “bracing myself for a future election such as 2008 or 2018, when everyone else can see the electoral tsunami headed for shore and our model stubbornly insists that it will be a mere ripple”. However, this year, the other factors in the model all favoured Democrats: the party had romped in special elections, and Donald Trump’s approval rating was abysmal. When we launched in April, the headline was that Democrats had a 94% chance of taking the House.That changed during the campaign’s final two weeks, because of a change in national polling that barely affected other models but jolted ours. When I first built the model, I found that in midterms, the share of voters who were undecided contained a useful signal: the more there were, the worse the president’s party did. It seemed intuitive that undecideds would break against the president in midterms, and the variable helped to distinguish years like 1994 (when Democrats were nearly tied in generic-ballot polling but lost badly) from 2022 (when Democrats had the same generic-ballot position but minimised their losses). So rather than applying a flat midterm penalty to the president’s party, I let it vary depending on the share of undecideds.
I hadn’t given this factor much thought since I built this model in 2017, because it didn’t matter much until now: between 1998 and 2022 the undecided share in midterms always landed between 9% and 13%. But this year, voters seemed to make up their minds abruptly: from October 11th to election day the undecided share dropped from 9.4% to 6.9% (see chart above). Our model expected around 74% of them to pick Democrats, but only 59% did. That led our model to trim a full point of Democrats’ predicted margin, causing their probability of winning the Senate to fall from 62% to 52% even as their position in polls of individual Senate races strengthened.
I was concerned about this pattern. The undecided share hadn’t been this low in a midterm since 1966, and I had no way to know whether the trend was genuine or whether pollsters had simply started “pushing leaners” to pick a side more than in the past. When I tested replacing this factor with a simple midterm effect, Democrats’ chances of winning the Senate rose all the way to 68%. But I couldn’t re-design the model two days before the election. The obvious lesson to draw from this mishap is that others are right and that no one can accurately predict polling errors. But I still see value in taking a different approach to everyone else. The conclusion I draw is more technical: models trained on small datasets like the 40-odd congressional elections for which we have polling are easy to over-fit, and doing extra sensitivity testing on potentially extreme values of the model’s inputs (such as the undecideds) could help ensure that it behaves as intended. I’m eager to keep going out on a limb and am not afraid to be proven wrong—as long as it’s for the right reasons.


